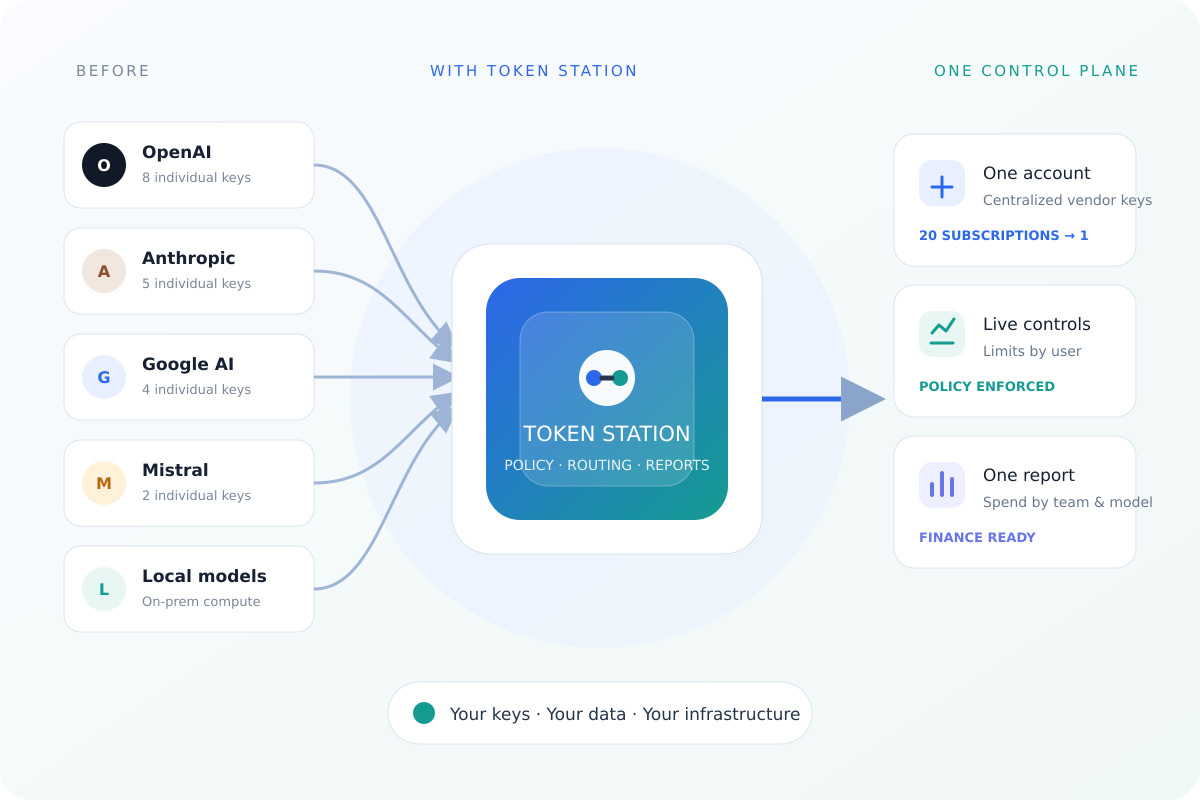
Token Station pools your team's coding plans and API keys in one private gateway. Its smart router sends each task to the right model, and its company brain turns what AI solves into knowledge the whole team can reuse. Buy fewer plans and see exactly who used what, and when.
“In 2026, the biggest budgeting risk isn't overspending. It's spending invisibly.”
FinOps Weekly
Token Station runs on your own servers. Your keys, your data, your rules.
Install Token Station on any Linux server you control, from an Olares Mini to a cloud VPS. We walk your team through the install during the pilot. No vendor lock-in.
Bring the coding plan subscriptions and API keys you already pay for into one shared pool, then invite your team. Requests spread across every plan, so no quota sits idle while a teammate is rate-limited, and everyone keeps the same AI tools.
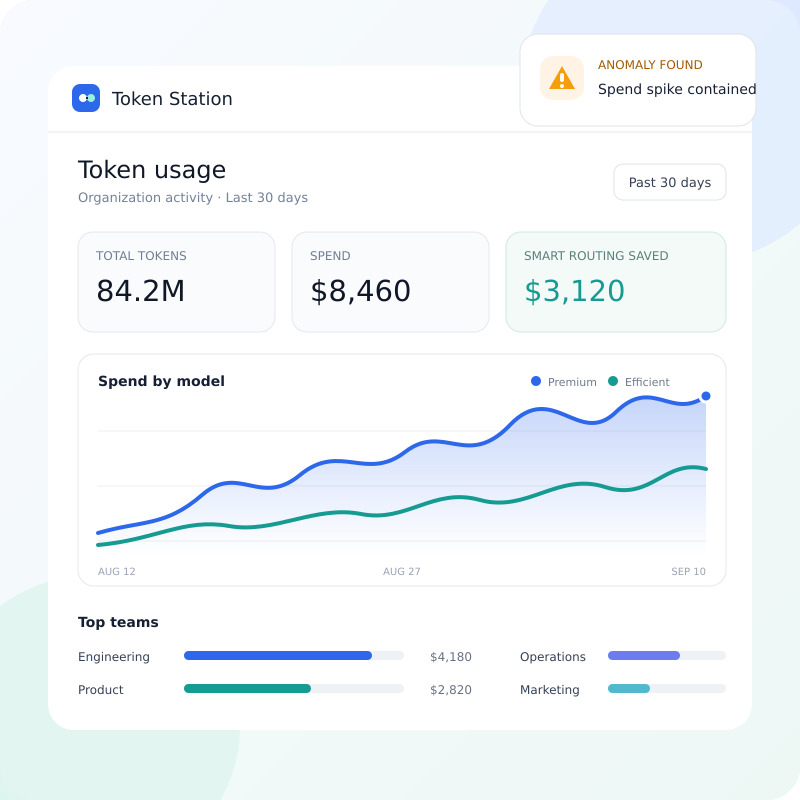
Smart routing selects the right model for each task automatically. Management gets per-user, per-department token reports. Finance can finally forecast AI spend.
Token Station analyzes how AI solves problems for your team and extracts that knowledge into a searchable "company brain". Anyone can look up how a problem was already solved, and future AI interactions build on what the team has learned instead of starting from zero.
Coding plan subscriptions are bought one per person, but usage is uneven: a few engineers hit their limits mid-week while other seats sit mostly idle. A private Token Station pools the plans your team already pays for and spreads requests across them, so spare quota covers your heaviest users and you stop buying more plans to keep them unblocked. Finance gets one invoice. IT gets one control plane.

Who used what model, when, and how many tokens. Department-level rollups. Daily, weekly, monthly trends. The reports your CFO has been asking for since ChatGPT launched.

Not every task needs a frontier model. Token Station's adaptive router directs simple queries to cost-efficient models and complex tasks to frontier models, with no change to your team's workflow.
2x+ cost savings with no drop in response quality by routing queries intelligently between large and small models.
40% reduction in large-model calls, with further improvements on adaptive routing.
When AI helps someone crack a hard problem, the answer usually stays buried in one person's chat history. Token Station can analyze how AI solves problems for your team and extract that knowledge into a searchable company brain, so the whole team and every future AI interaction can use it.
Token Station looks at how AI worked through your team's problems: the question, the approach, and the answer that worked.
The reusable knowledge goes into your company brain instead of disappearing with the chat.
Anyone on the team can search it, and future AI interactions draw on it.
$10 per employee per month, with no seat fees for the first 30 days. Two ways to handle AI vendor keys. Token Station has 30+ supported models from leading labs, plus coding plans.
| Feature | On-Prem: bring your own keys$10per employee / monthAI token costs bill directly to your existing vendor accounts. | Cloud: use our keys$10per employee / monthPlus token usage billed in $50 increments at published provider rates, zero markup. |
|---|---|---|
| Best for | Teams already paying for coding plans or API keys | New deployments and fully consolidated billing |
| Vendor accounts | Your own coding plans and API keys. We never touch your vendor billing. | Not needed: we provide pooled vendor accounts |
| AI token costs | Billed direct to your vendor | Metered in $50 increments, zero markup |
| Pooled coding plans, fully used across the team | ✓ | ✓ |
| Gateway and smart routing | ✓ | ✓ |
| Per-user token limits and reports | ✓ | ✓ |
| Management usage dashboards | ✓ | ✓ |
| Key management | Centralized | None: instant setup |
| Billing | Works with your existing vendor accounts | Fully consolidated |
| Start your On-Prem pilot | Start your Cloud pilot |
Requests to cloud models go from your own Token Station to the AI providers, just as they would if your team used those tools directly. When your pool and routing span several labs, no single upstream AI sees your team's complete data. For sensitive work, route requests to local models that stay inside your network, or turn on the optional PII filter to mask or reject personal data before it reaches a cloud AI.
Coding plans are bought one per person, but usage is uneven: a few people hit their limits mid-week while other seats sit mostly idle. Token Station puts the coding plan subscriptions and API keys your team already pays for into one pool and spreads requests across it, so spare quota covers your heaviest users and you stop buying extra plans to keep them unblocked. Per-user limits stop any one person from draining the pool, and usage reports show who used what.
Minimal disruption. Employees point their AI tools at the Token Station gateway endpoint instead of directly at OpenAI or Anthropic. Most tools support custom base URLs. Setup per user takes under 5 minutes. The smart routing happens transparently, so they get the same responses, often faster and cheaper.
Token Station analyzes query complexity and routes simple tasks (summarization, basic Q&A, formatting) to smaller, cheaper models, and complex reasoning or code tasks to your preferred premium model. Based on RouteLLM (ICLR 2025) research, this achieves 2x+ cost savings with no measurable quality loss. You can tune the cost/quality balance per department or disable routing entirely.
It's an optional feature you can turn on when your team is ready. Token Station analyzes how AI solves problems for your team and extracts that knowledge into a searchable company brain, stored locally on your own Token Station. Anyone on your team can look up how a problem was already solved, and future AI interactions build on what the team has already learned.
Pilot partners keep $10 per employee per month as founder pricing for as long as the deployment stays active. Token costs sit outside that seat fee: on On-Prem they bill straight to your own vendor accounts, and on Cloud they are metered in $50 increments at published provider rates with zero markup.
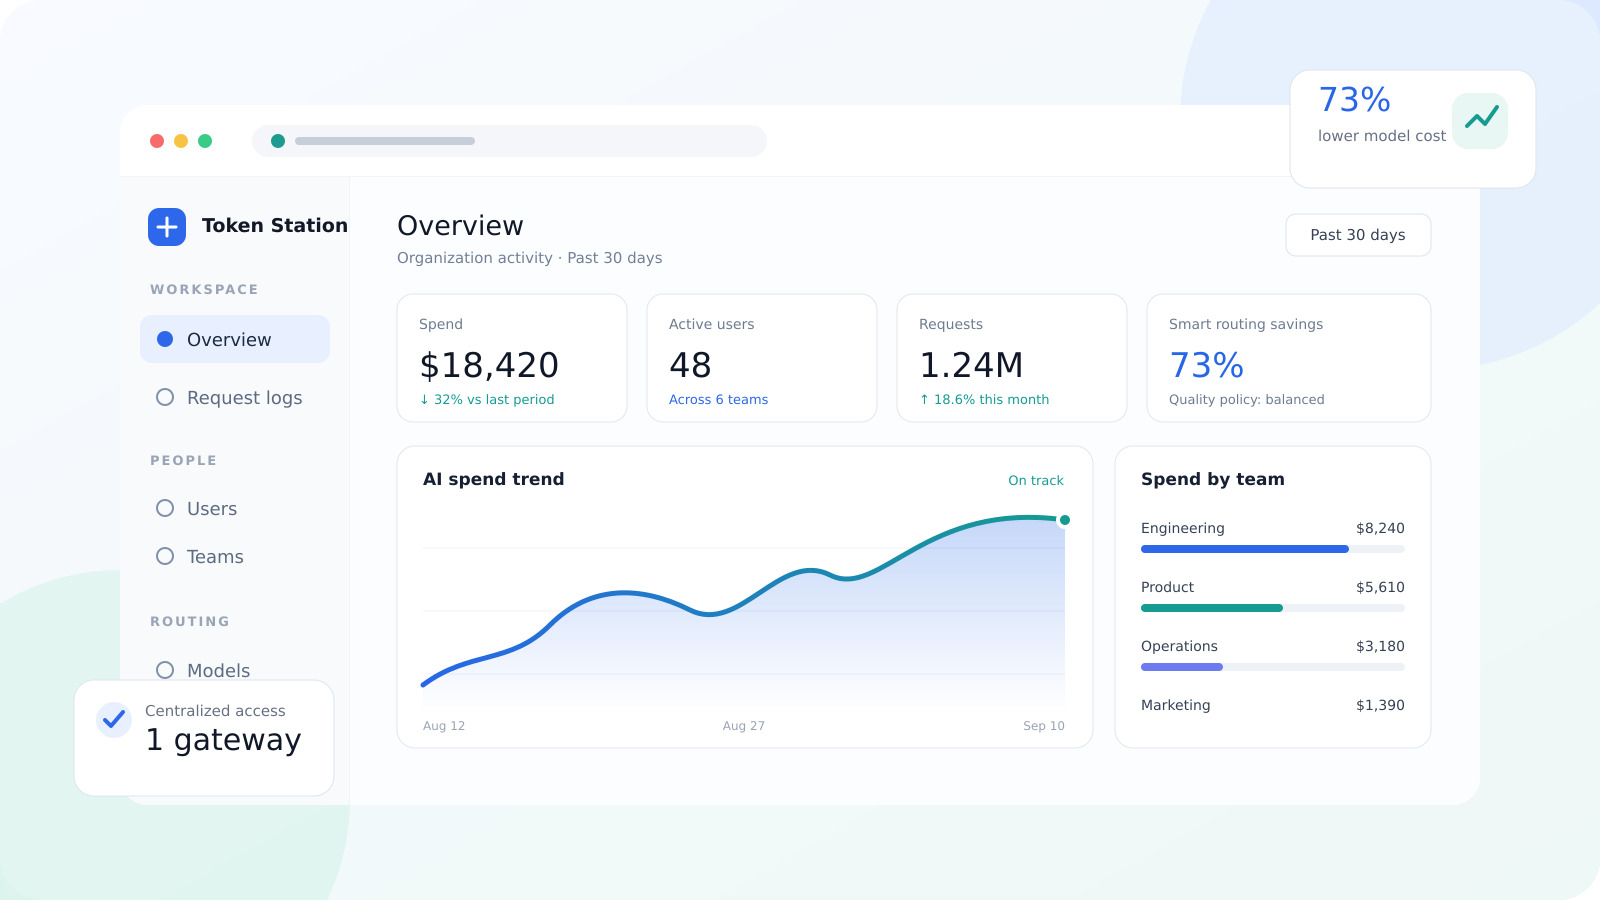
Join the pilot. Get full visibility, one consolidated bill, and up to 73% lower token costs, all on your own infrastructure.